Yichen Guo

Yichen Guo

AI Research

Nanyang Technological University

Seeking PhD · Spring / Fall 2027

Publications

Google Scholar

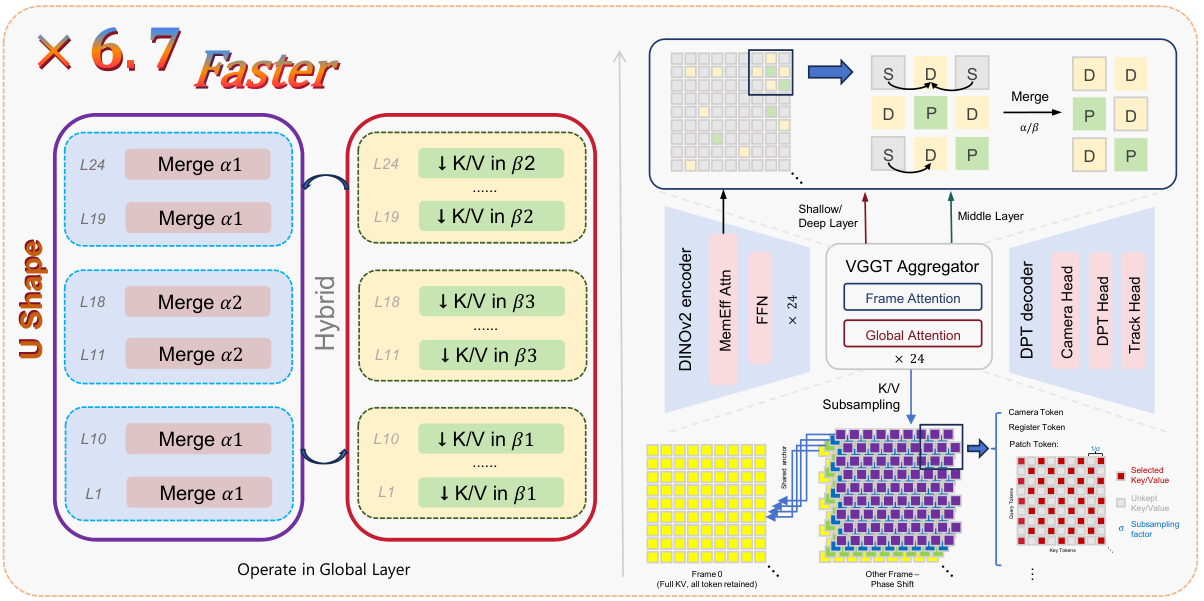
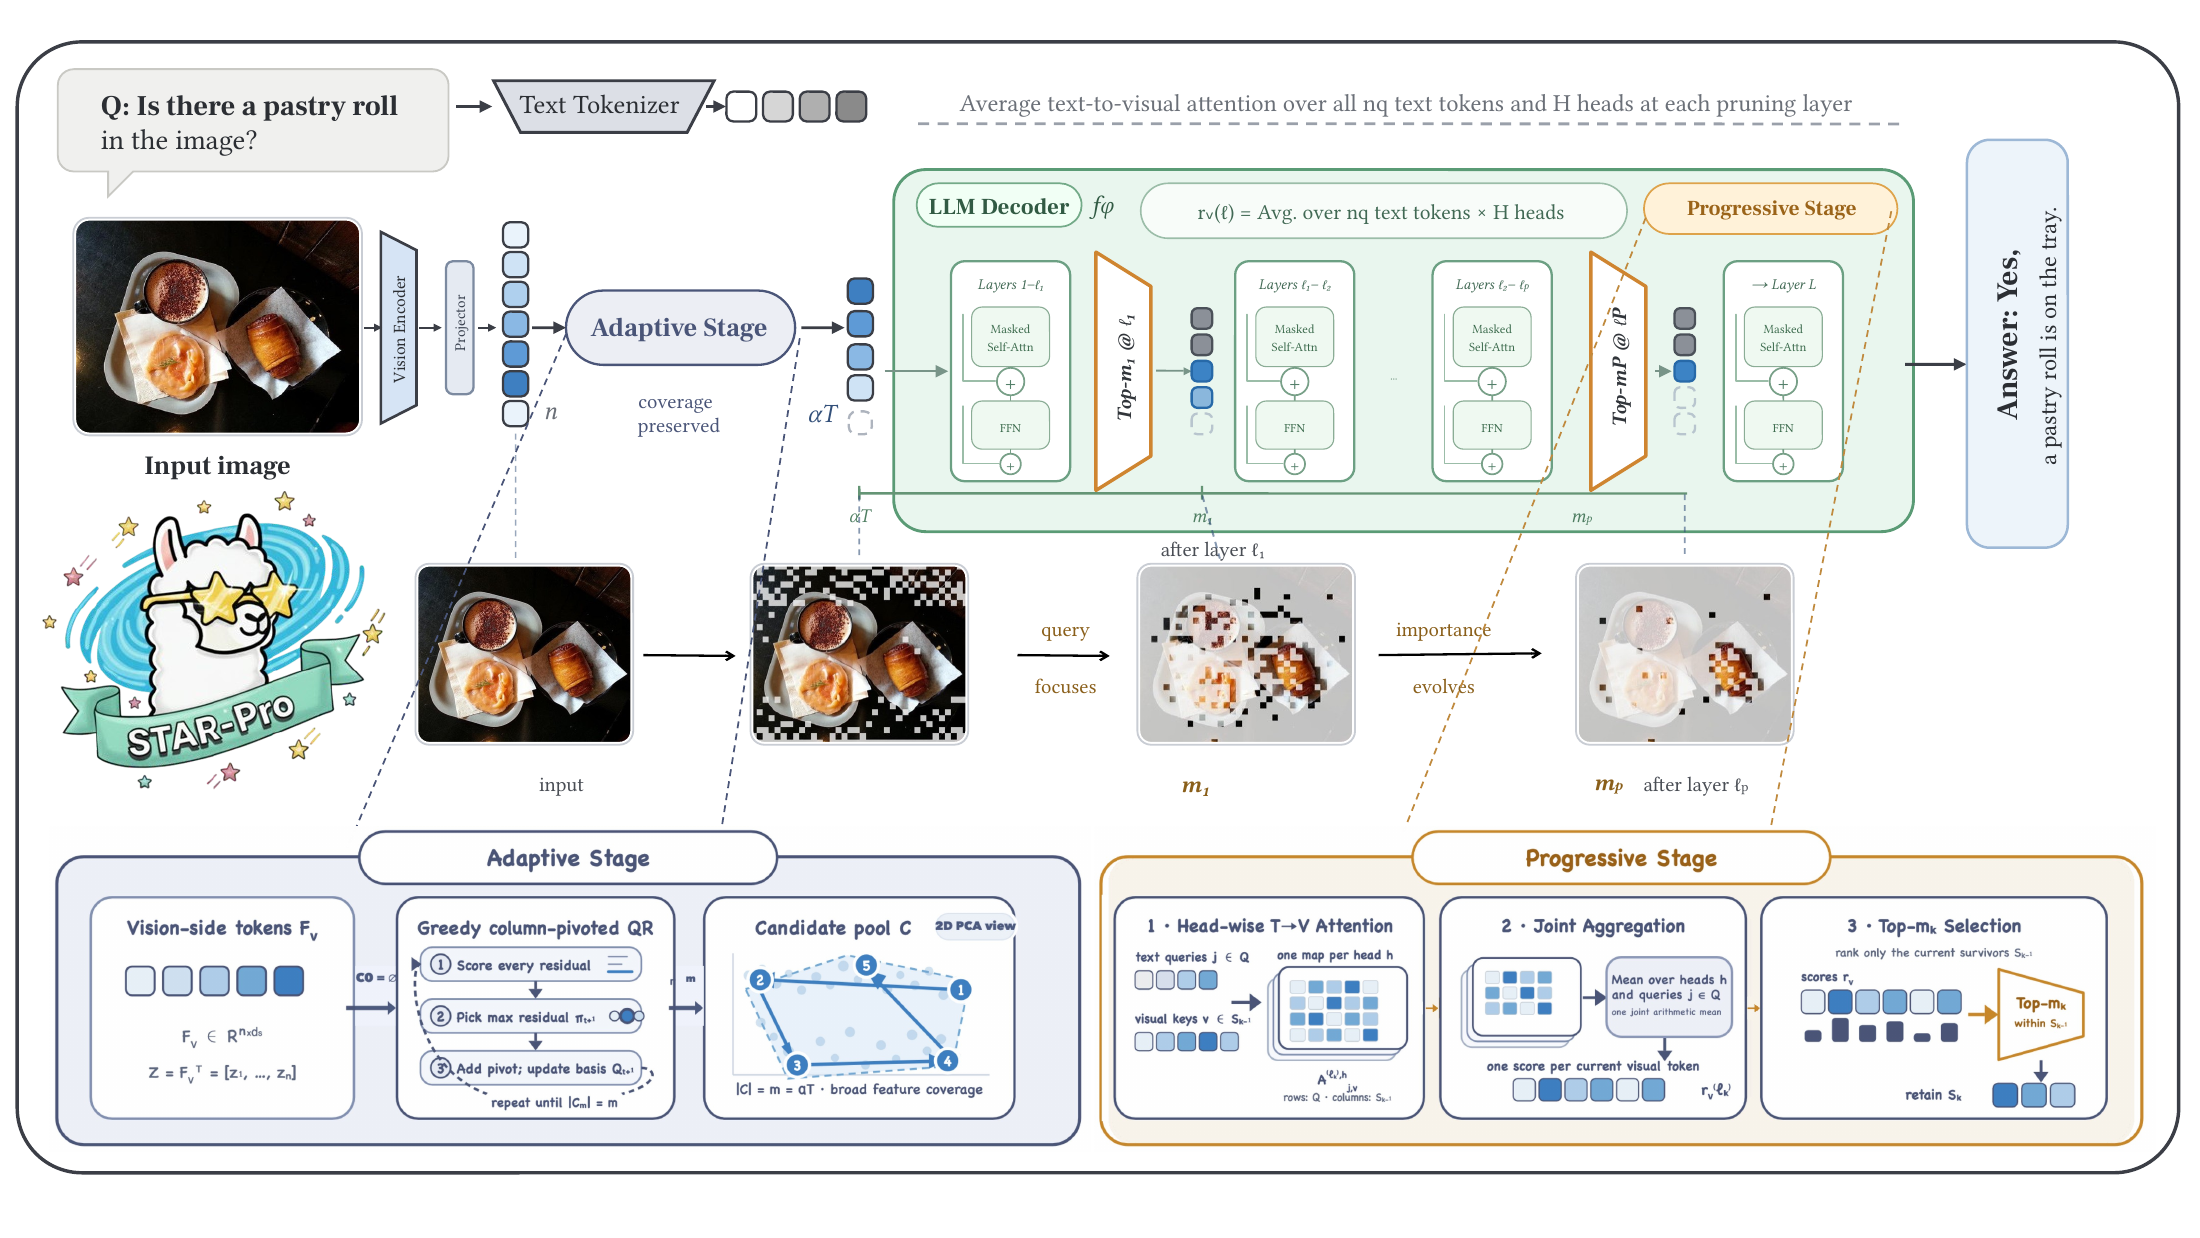
  1. STAR-Pro's Adaptive Stage preserves visual feature coverage, followed by progressive token refinement across decoder layers. arXiv

    STAR-Pro: Stage-Wise Token Adaptive Reduction with Progressive Refinement for Efficient Large Vision-Language Models

    Yichen Guo, Tinghao Wang, Qizhe Zhang, Lingbei Meng, Yuan Zhang, Jiajun Cao, Hao Jiang, Chenwei Wu, Jixian Wu, Sixiang Chen, Tao Luo, Hongyang Cheng, Kai Tang, Chenxi Li, Renyuan Li, Xiande Huang, Wenya Wang, Shanghang Zhang

    Under review · 2026 · Co-first author

    Training-free visual token reduction that preserves feature coverage, then progressively refines retained tokens as language and vision interact.

    My contribution: As a co-first author, I contributed to the design of adaptive-to-progressive token pruning and its evaluation across vision-language architectures.
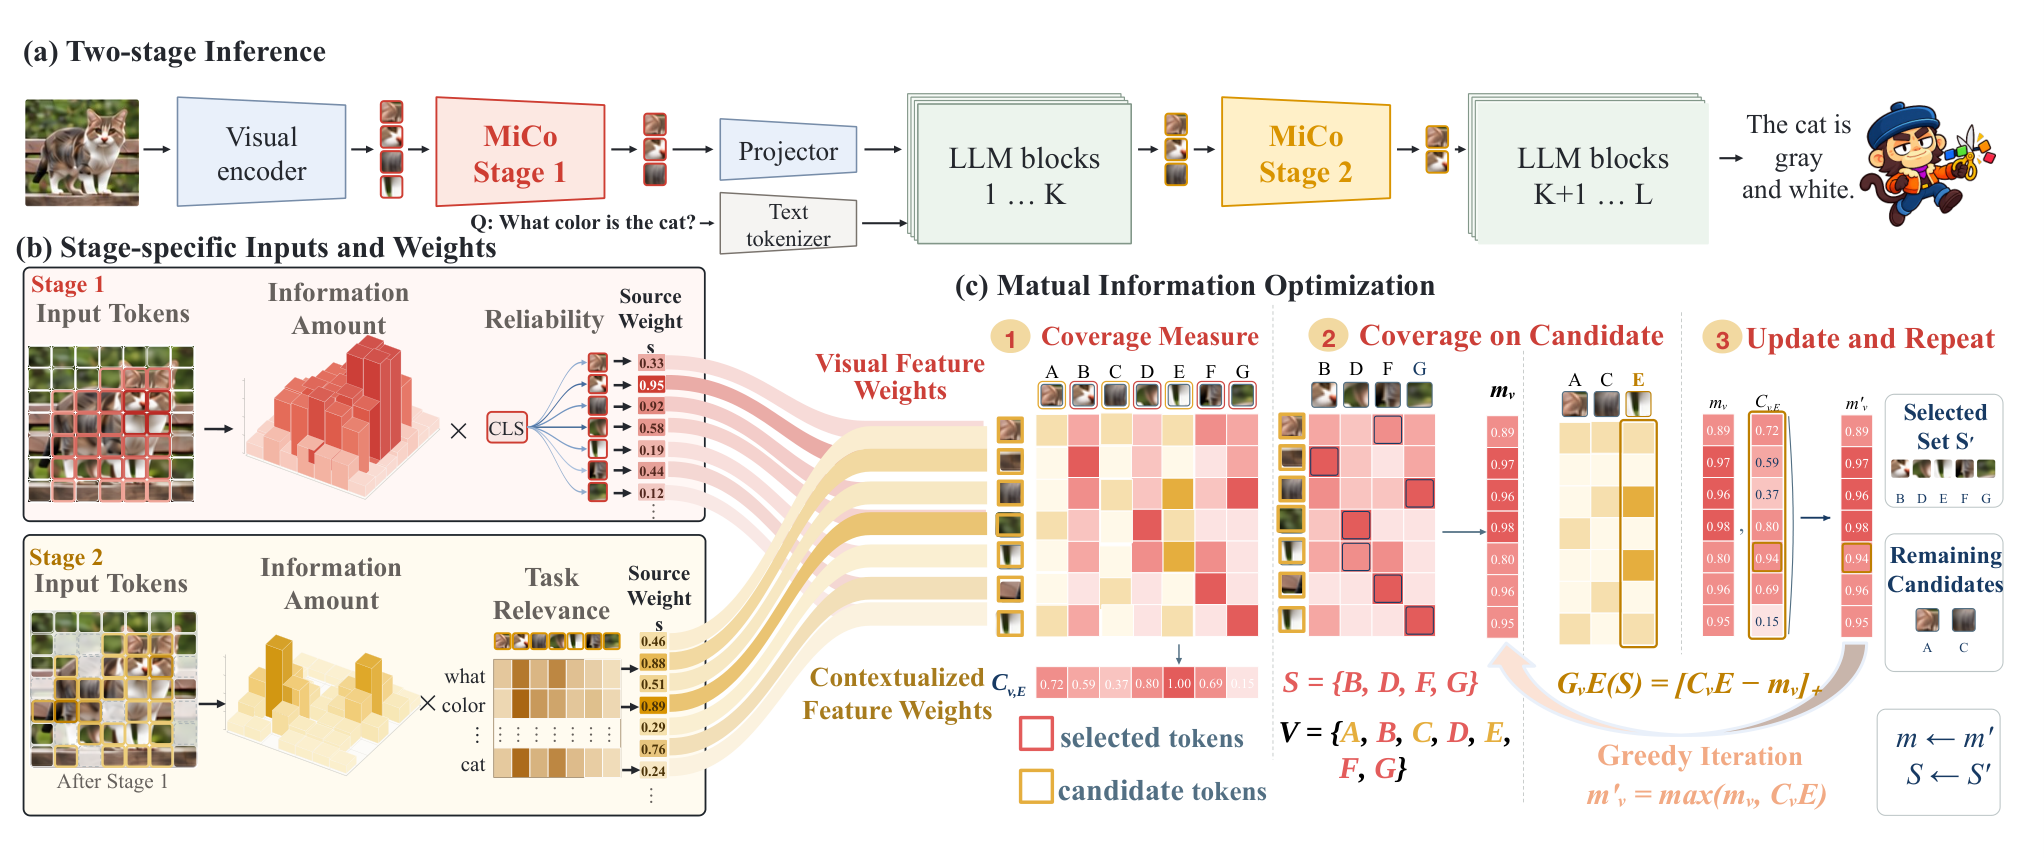
  2. MiCo's two-stage pruning framework: visual candidate selection, task-aware refinement, and greedy mutual information coverage optimization. arXiv

    MiCo: Mutual Information Coverage Optimization through Semantic Erasure Modeling for Efficient MLLM Inference

    Tinghao Wang, Yichen Guo, Qizhe Zhang, Yuan Zhang, Weimin Ouyang, Rui Huang, Jiajun Cao, Sixiang Chen, Hao Jiang, Jixian Wu, Zheng Lu, Bofan Zhu, Renyuan Li, Shanghang Zhang

    Preprint · 2026 · Co-first author

    Training-free, two-stage visual token pruning that maximizes mutual information coverage: select a representative visual pool, then refine it with task-aware signals.

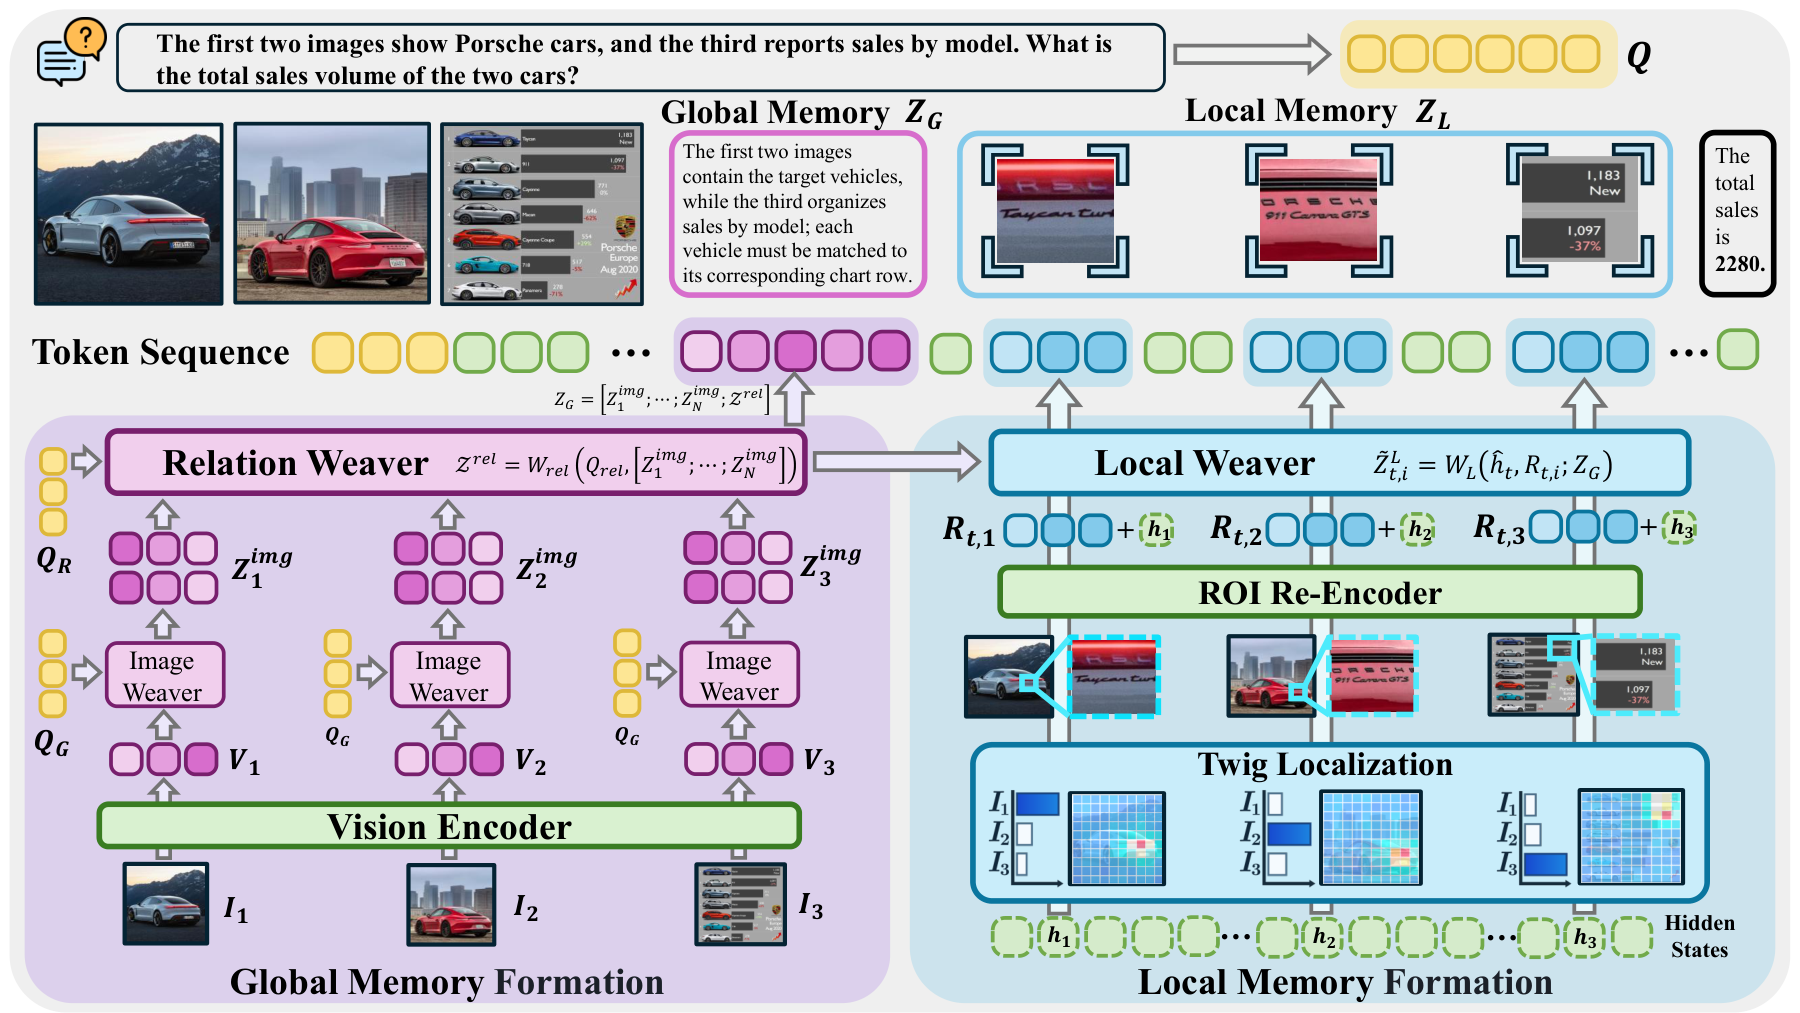
  3. ReMAP combines global scene context, local region evidence, and reinforcement-learned memory access during multimodal reasoning. arXiv

    ReMAP: Restoring the Perceptual Cycle with Reasoning-Time Latent Visual Memory

    Hao Jiang*, Zhanyu Guo*, Chenwei Wu†, Yichen Guo†, Qizhe Zhang, Junchi Yao, Jixian Wu, Jinhao You, Kai Tang, Jiajun Cao, Tinghao Wang, Mengyu Wang, Leo Anthony Celi, Shanghang Zhang

    * Equal contribution · † Project leaders

    Preprint · 2026 · Project Leader

    Global and local latent visual memories restore visual grounding during reasoning; a reinforcement-learning policy decides when to retrieve each type of evidence.

    My contribution: Project leader, working on latent visual memory and learned memory-access policies for multimodal reasoning.

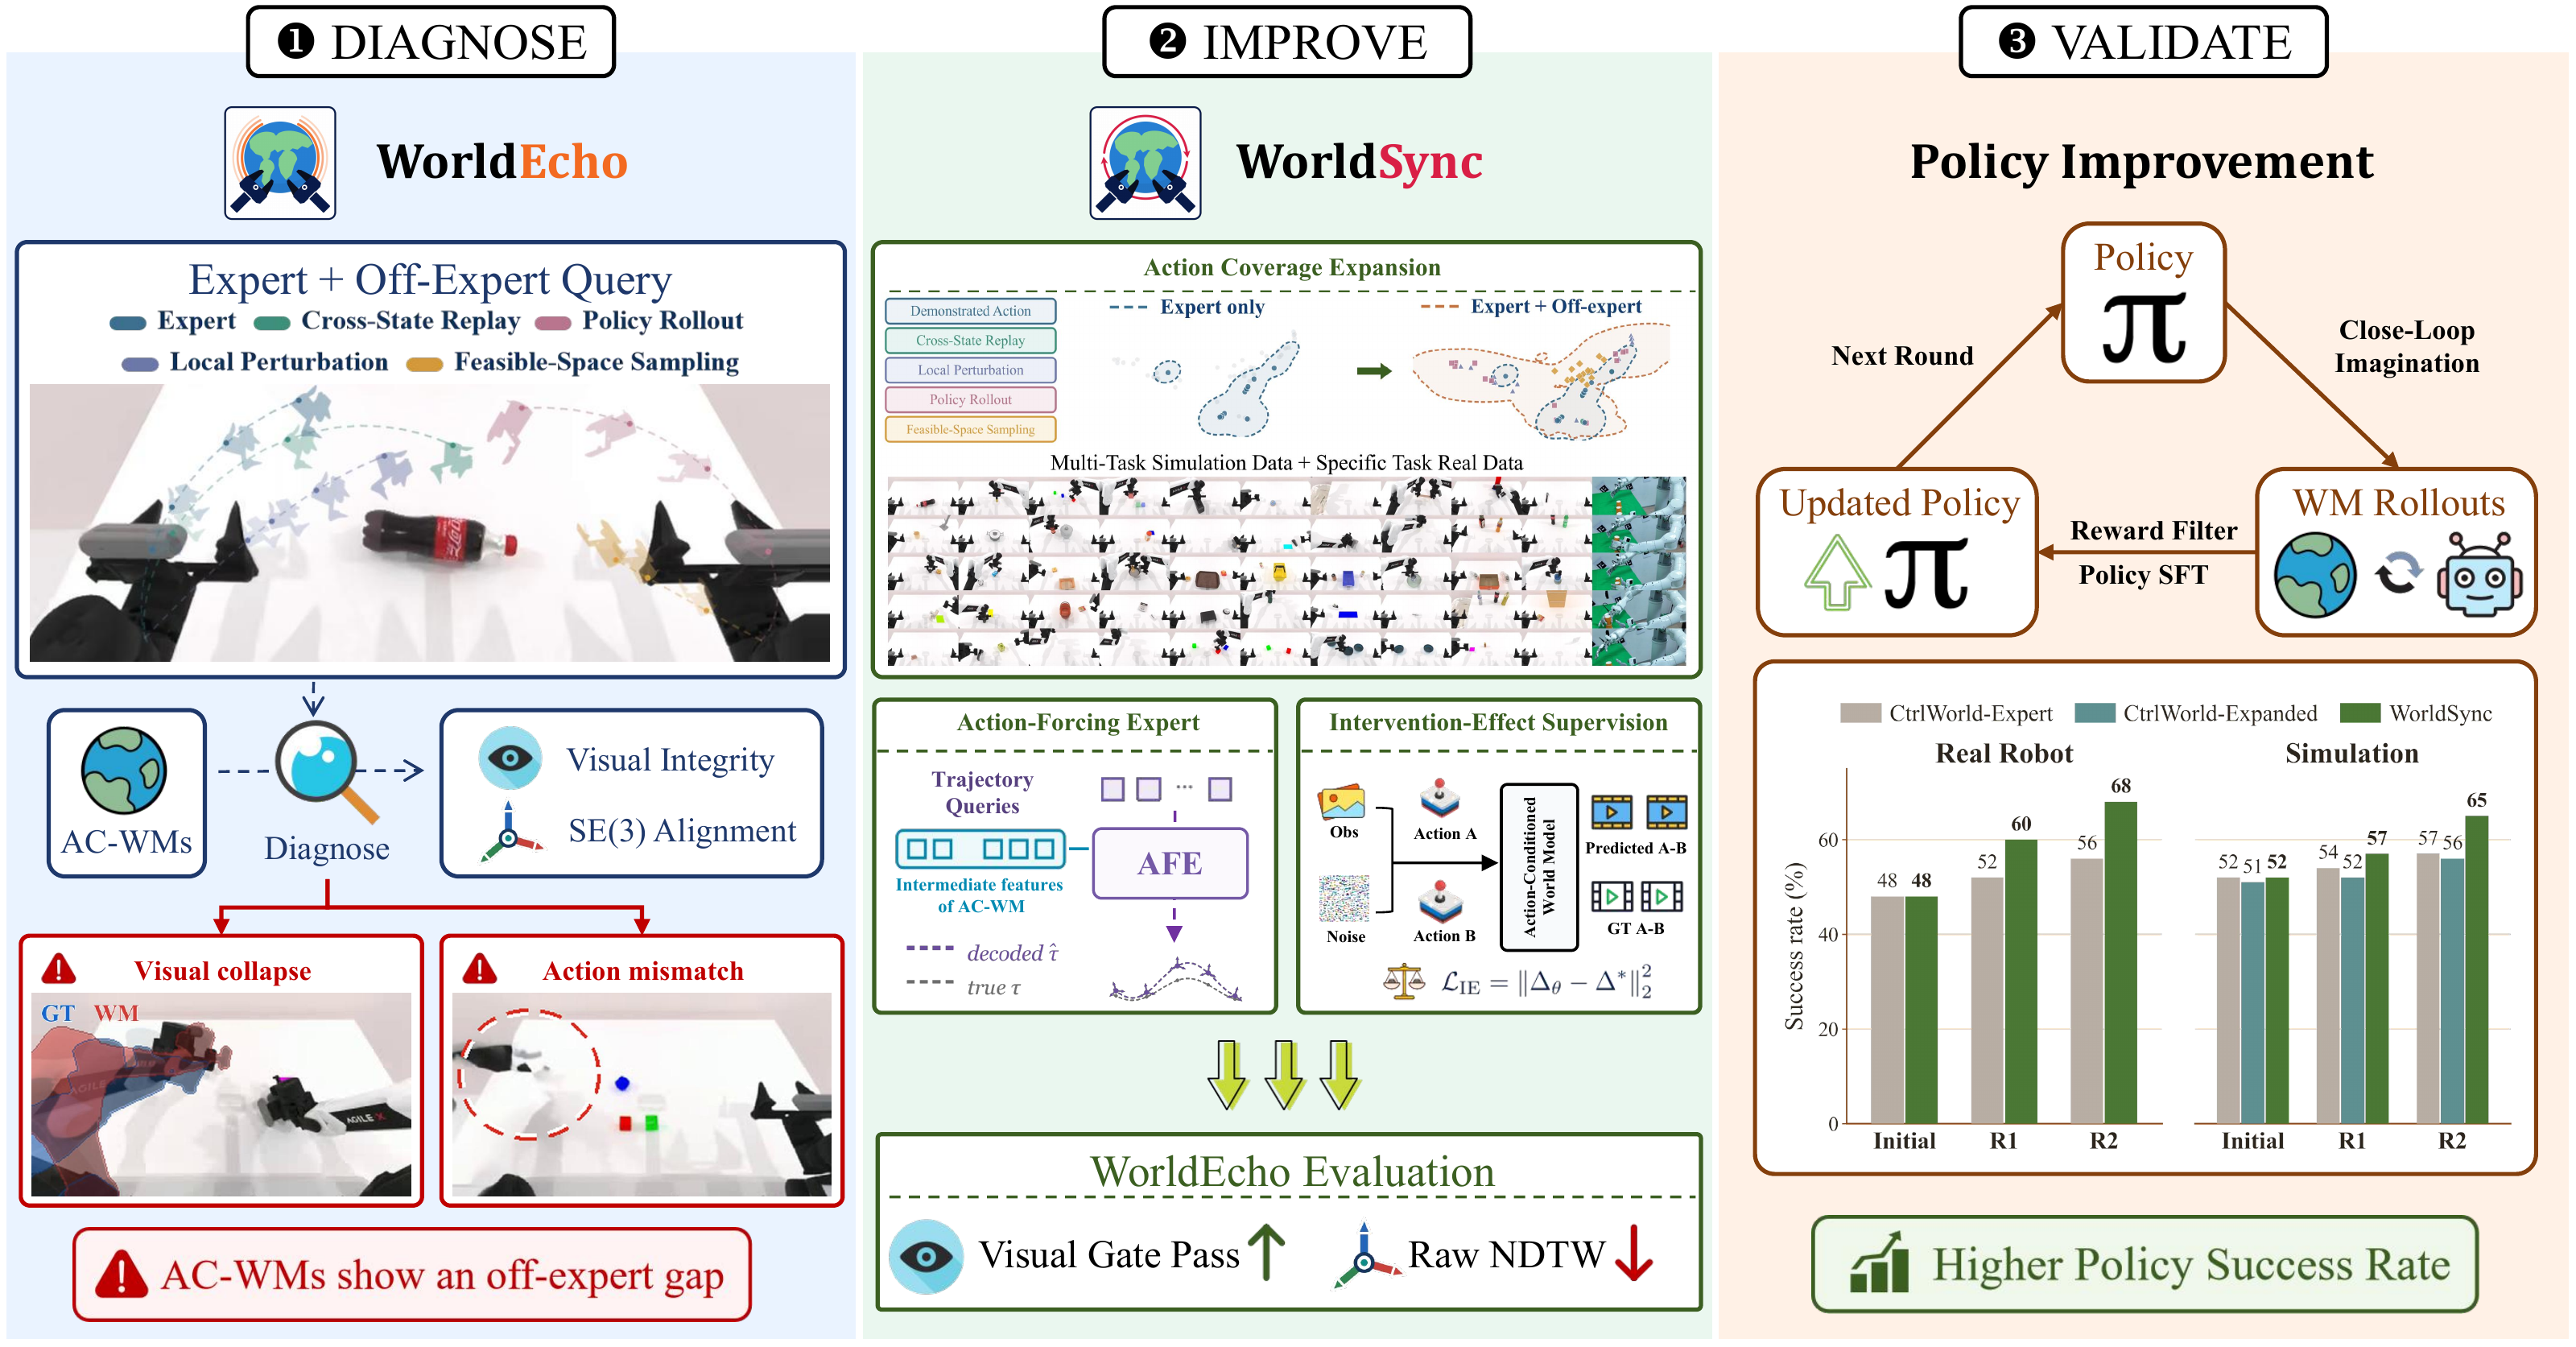
  4. WorldEcho and WorldSync: diagnosing action following, aligning world models, and validating policy learning. arXiv

    Do Robotic World Models Really Follow Actions? Diagnosing and Aligning Action-Conditioned Generation for Policy Learning

    Sixiang Chen, Jiaming Liu, Jixian Wu, Yichen Guo, Tinghao Wang, Siyuan Qian, Hao Chen, Jiajun Cao, Jian Tang, Shanghang Zhang

    Preprint · 2026 · Core contributor

    WorldEcho diagnoses action-following failures; WorldSync aligns generation with robot dynamics to support policy learning.

    My contribution: As a core contributor, I work on understanding and improving action following in robotic world models.

    Dataset access is currently restricted; data upload is pending.

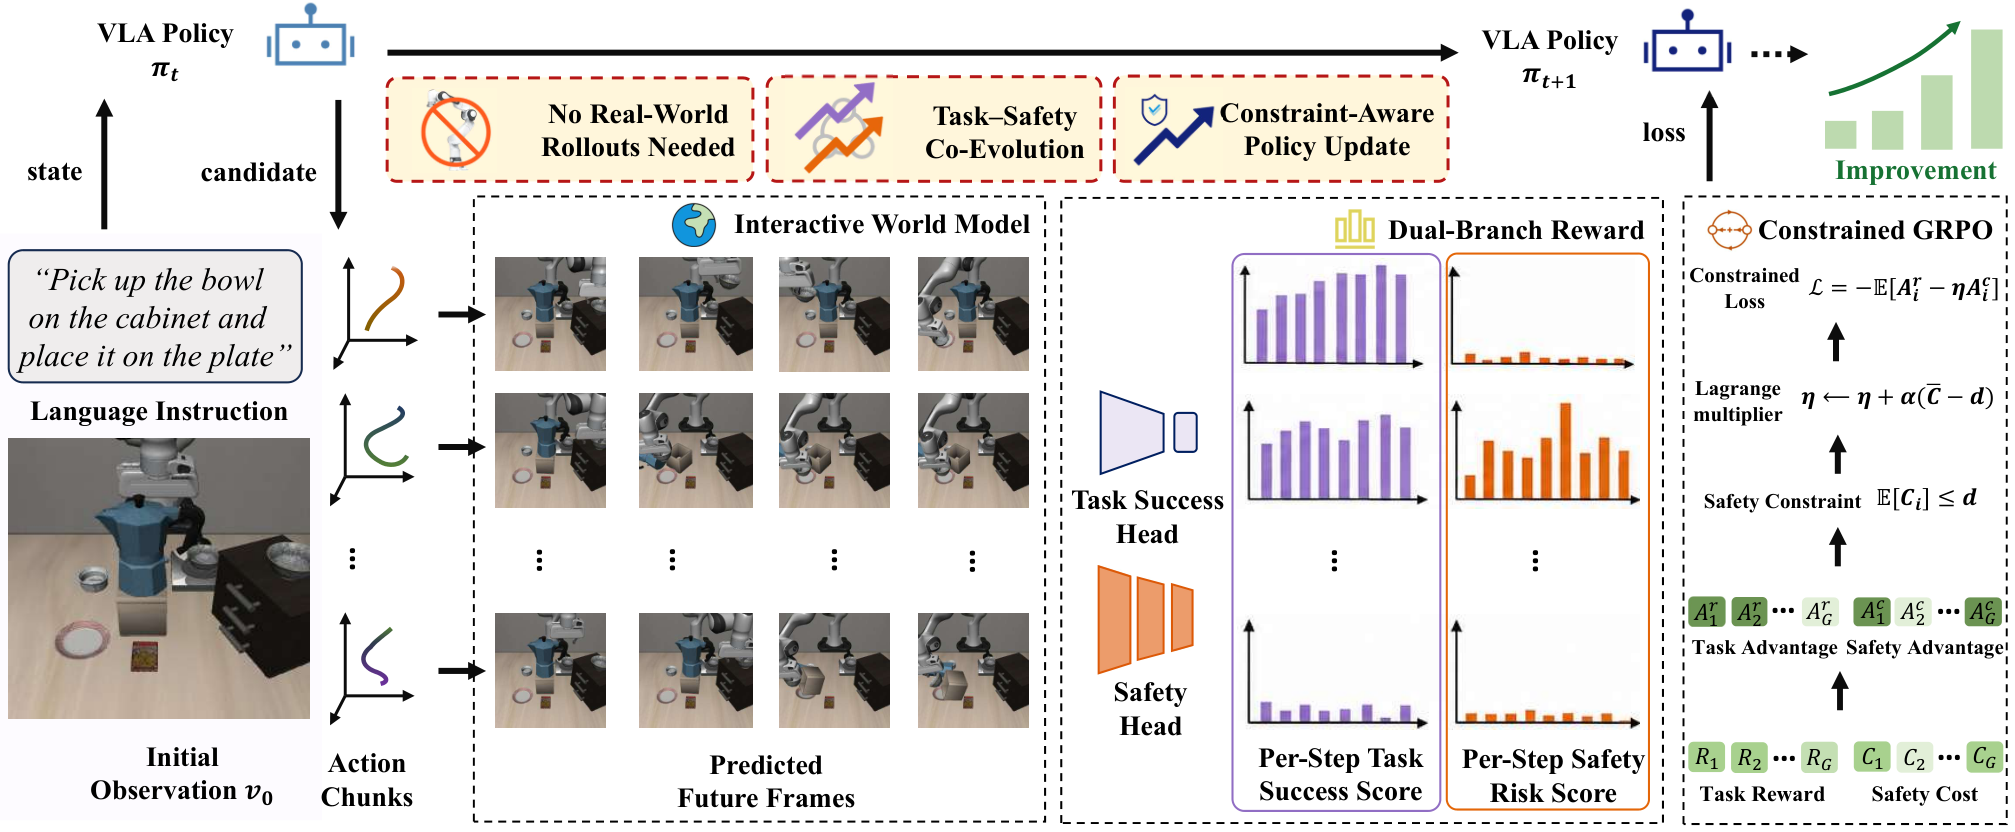
  5. SafeDojo's pipeline combines action-conditioned world-model rollouts, task-success and safety evaluation, and constrained GRPO policy updates. CoRL 2026

    SafeDojo: Safe Reinforcement Learning for VLA via Interactive World Model

    Kai Tang, Peidong Jia, Zhong Chu, Jixian Wu, Rui Ma, Jiajun Cao, Fangyuan Zhao, Sixiang Chen, Yichen Guo, Xiaowei Chi, Chun-Kai Fan, Kevin Zhang, Jinchang Xu, Fubing Yang, Weishi Mi, Xiaozhu Ju, Jian Tang, Shanghang Zhang

    CoRL 2026 · Accepted · Co-author

    Safe reinforcement learning for VLA policies through imagined rollouts in an interactive world model, balancing task progress and safety.

  6. SeeMe: Mitigating Hallucinations in Large Vision-Language Models through Effective Visual Token Engineering

    J. You*, K. Tang*, Yichen Guo, C. Li, H. Li, Y. Qu, X. Huang

    Manuscript · 2026 · Co-author

    Visual token engineering to improve consistency and reduce hallucinations in vision-language models.

  7. MAP: Mitigating Hallucinations in Large Vision-Language Models with Map-Level Attention Processing

    C. Li*, Yichen Guo*, B. Qian, J. You, K. Tang, Y. Du, Z. Zhang, X. Huang

    Manuscript · 2026 · Equal contribution

    Training-free decoding with map-level attention processing to mitigate hallucinations in vision-language models.

  8. STAR: Stage-Wise Attention-Guided Token Reduction for Efficient Large Vision-Language Models Inference

    Yichen Guo, H. Li, Z. Zhang, J. You, K. Tang, X. Huang

    Manuscript · 2025 · First author

    Earlier STAR manuscript on two-stage, training-free visual token reduction; the current preprint is STAR-Pro.

  9. Mitigating Hallucinations via Inter-Layer Consistency Aggregation in Large Vision-Language Models

    K. Tang*, J. You*, X. Ge, H. Li, Yichen Guo, X. Huang

    Manuscript · 2025 · Co-author

    Training-free decoding that aggregates inter-layer representations to improve semantic consistency and reduce hallucinations.

Powered by Jekyll and the Minimal Light theme.

Research figure

Scroll to inspect the full figure. Press Escape to close.