I am also a Research Affiliate at the PBC School of Finance, Tsinghua University, working under the guidance of Prof. Xiaoyan Zhang. Previously, I interned with Tencent LightSpeed Studios' Singapore team.
My research interests center on world models and AI agents, with a focus on action-conditioned generation, policy learning, agent harnesses, and post-training for tasks such as robotic manipulation, trading algorithms, market analysis, and the replication of econometric studies. I also study the efficiency and reliability of vision-language models (VLMs).
I am seeking PhD opportunities starting in Spring or Fall 2027. Feel free to contact me at yichen013@e.ntu.edu.sg to discuss research ideas, PhD opportunities, or potential collaborations. Recommendations are also welcome.
News & Milestones
🎉 ProbTraj accepted as a poster at the NeurIPS 2026 Workshop on Foundation Models for Temporal Systems! Congratulations to the ProbTraj team!
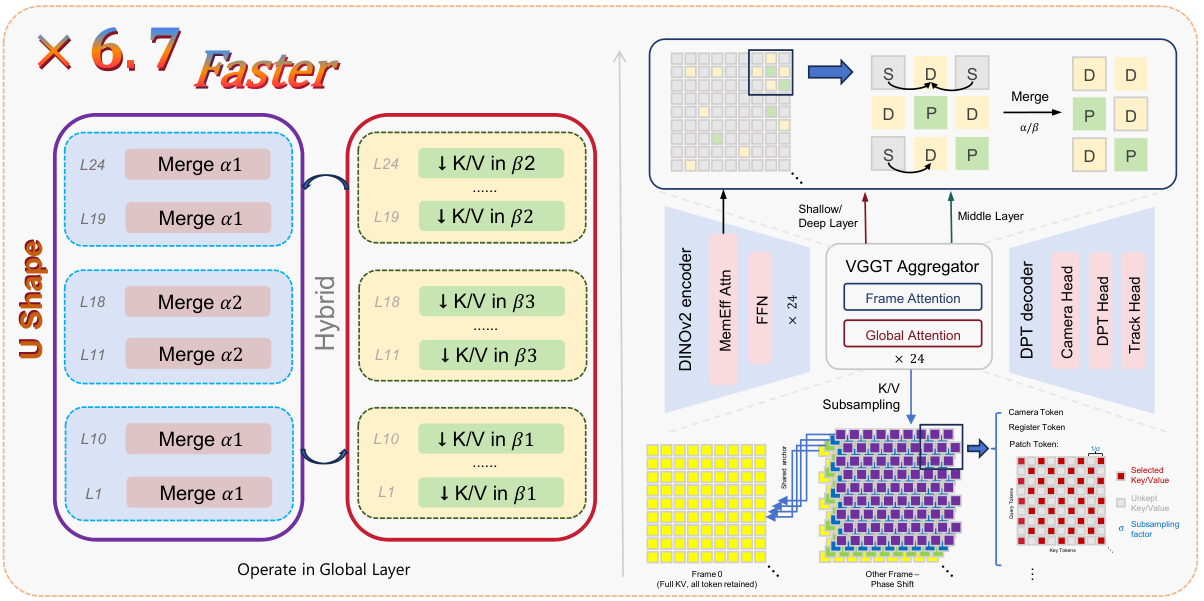
🎉 RegimeVGGT accepted to NeurIPS 2026! Congratulations to Jinhao You on this excellent work!
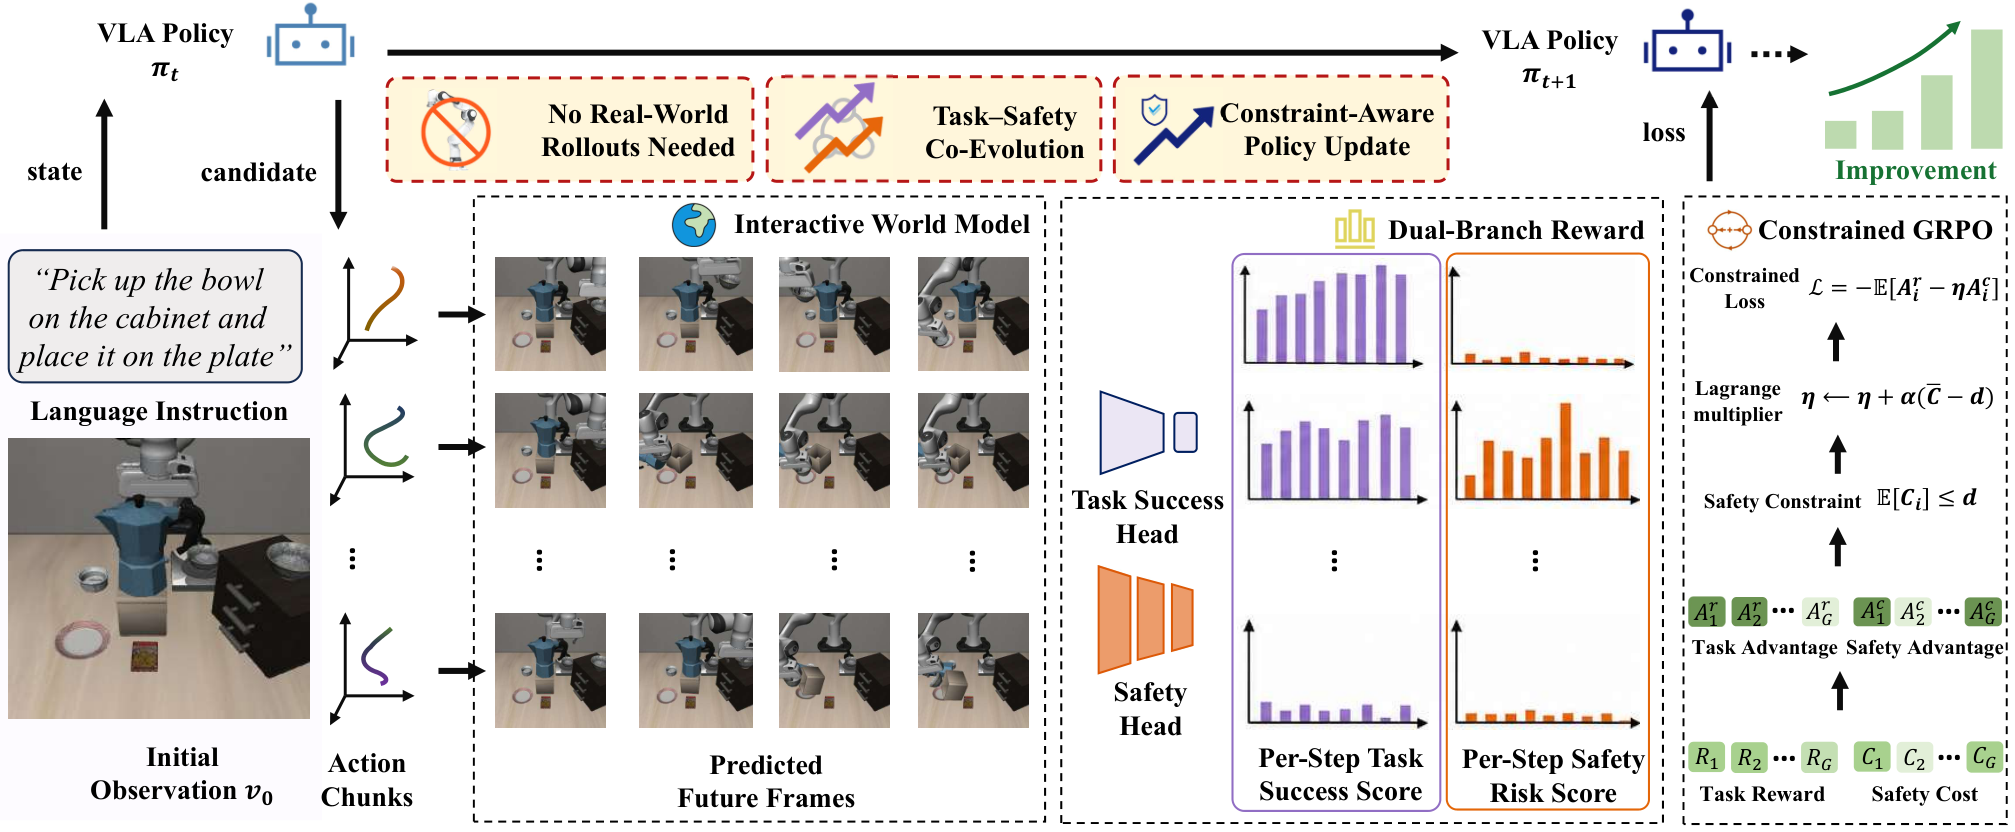
🎉 SafeDojo accepted to CoRL 2026! Congratulations to Kai Tang on this excellent work!
🔬 Joined the PBC School of Finance, Tsinghua University, as a Research Affiliate. Many thanks to Prof. Lin William Cong and Prof. Xiaoyan Zhang for this opportunity!
🔬 Joined GIFTS at Nanyang Technological University (NTU) as a Research Affiliate, under the supervision of Prof. Lin William Cong.
🎓 Began my Master of Engineering (by Research) at Nanyang Technological University (NTU), supervised by Prof. Wenya Wang.
💼 Joined Tencent LightSpeed Studios’ Singapore team.
🔬 Joined the Human Machine Intelligence (HMI) Lab at Peking University. Many thanks to Prof. Shanghang Zhang for this invaluable opportunity!
Research Interests
World Models: Action-conditioned generation, action following, policy training and learning, and unified models, with applications in robotic manipulation.
AI Agents: Agent harnesses, agentic capabilities such as autonomous planning and tool use, and post-training through supervised fine-tuning (SFT) and reinforcement learning (RL), with applications in trading algorithms, market analysis, and the replication of econometric studies.
Vision-Language Models (VLMs): Visual token reduction, efficient inference, and hallucination mitigation to improve model efficiency and reliability.
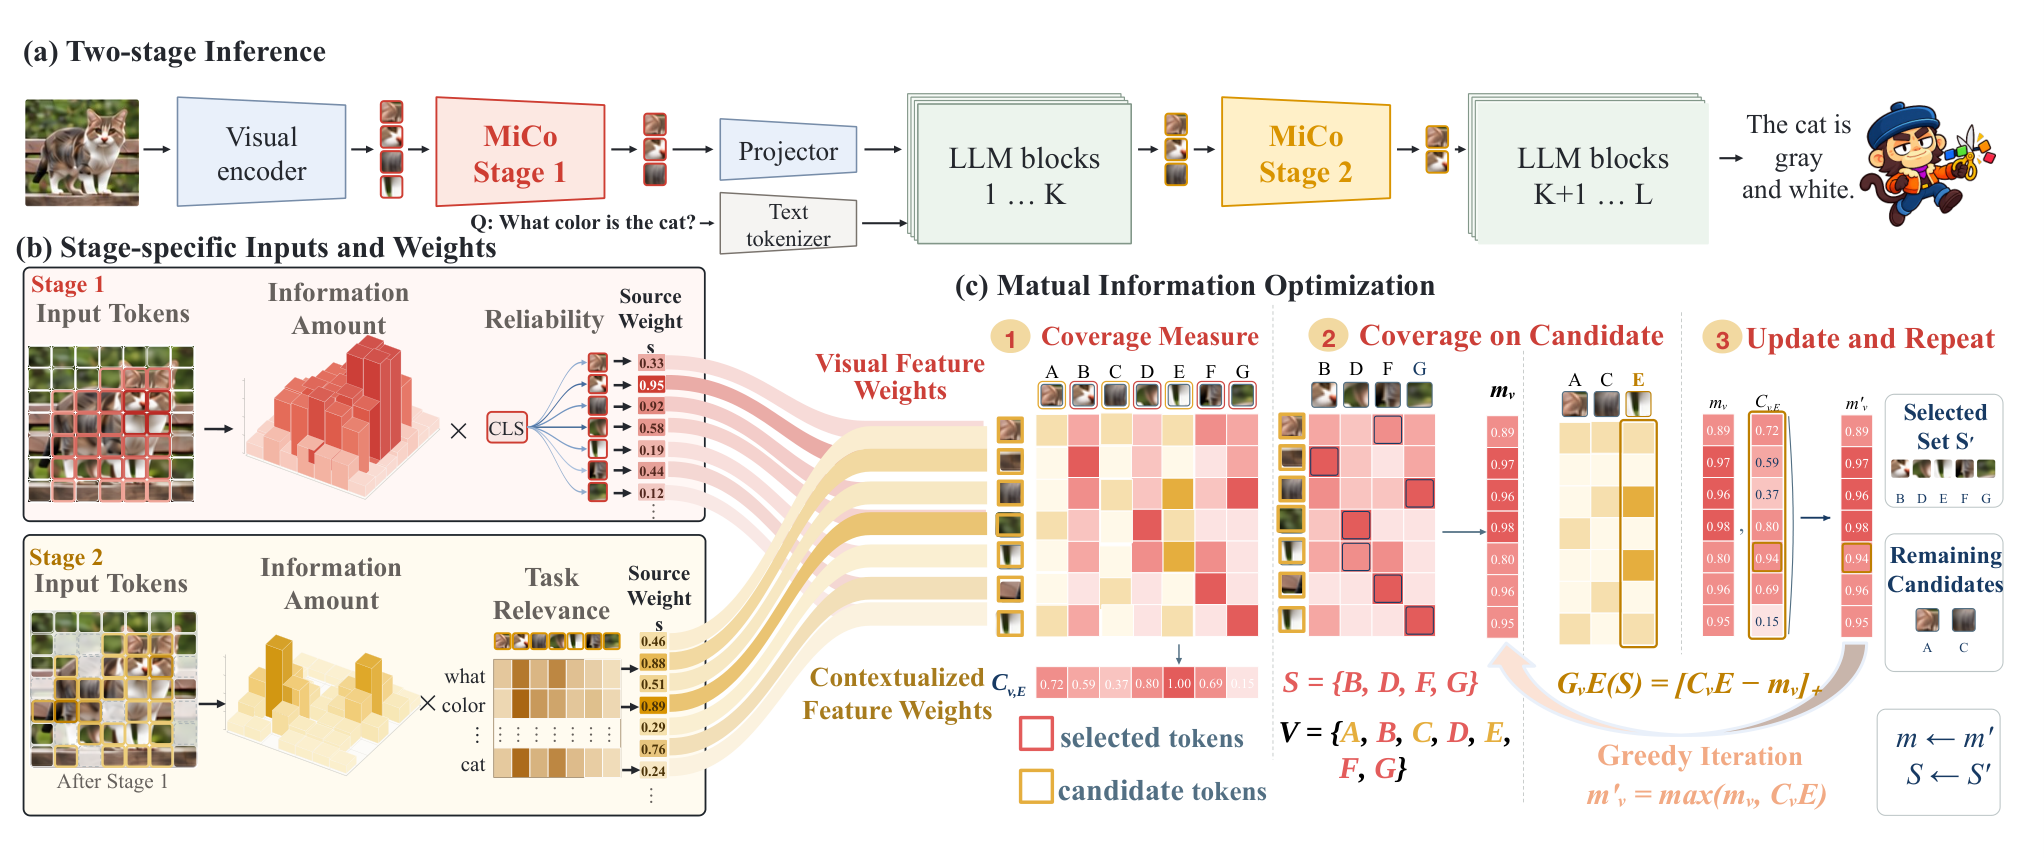
Training-free, two-stage visual token pruning that maximizes mutual information coverage: select a representative visual pool, then refine it with task-aware signals.
Hao Jiang*, Zhanyu Guo*, Chenwei Wu†, Yichen Guo†, Qizhe Zhang, Junchi Yao, Jixian Wu, Jinhao You, Kai Tang, Jiajun Cao, Tinghao Wang, Mengyu Wang, Leo Anthony Celi, Shanghang Zhang
* Equal contribution · † Project leaders
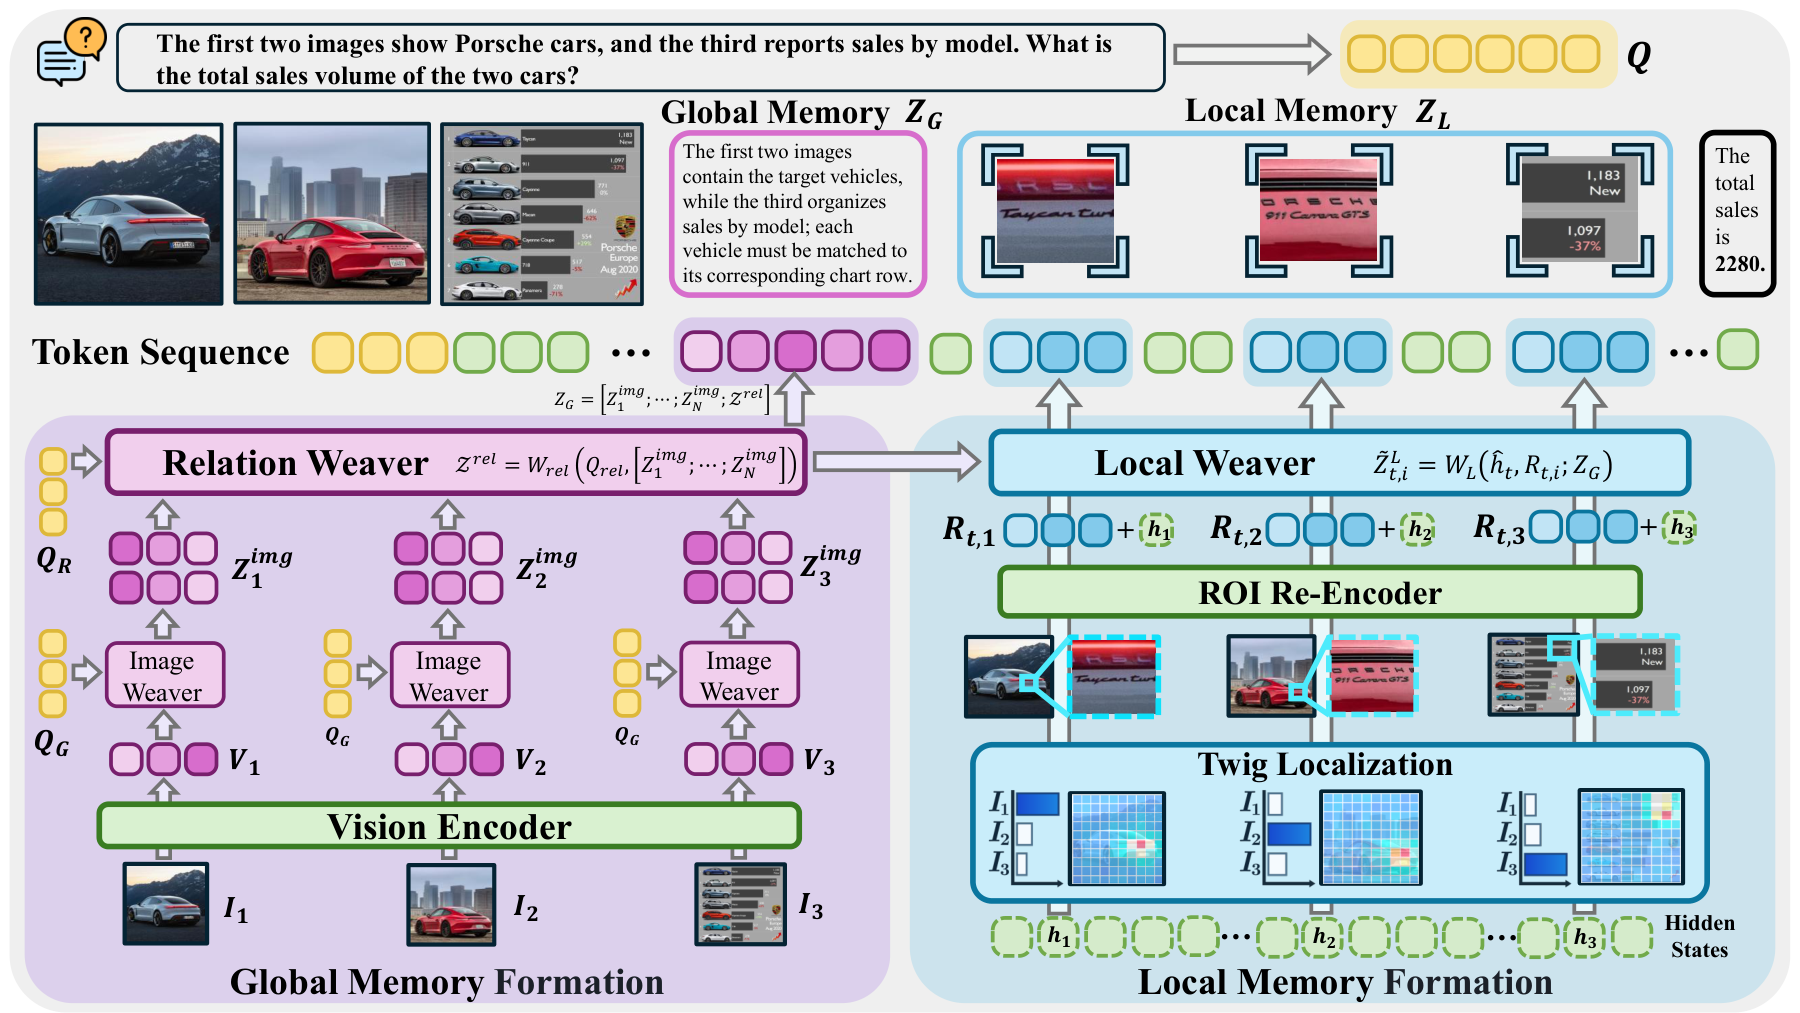
Global and local latent visual memories restore visual grounding during reasoning; a reinforcement-learning policy decides when to retrieve each type of evidence.
Project Leader
Project leader, working on latent visual memory and learned memory-access policies for multimodal reasoning.
Analyzed 1,740 human ratings of eight financial AI systems across 50 tasks using matched question–rater comparisons, two-way bootstrap uncertainty estimates, and fixed-effects models.
Diagnosed financial-reasoning failures through six-dimensional error decomposition and response-level evidence audits; developed technical reports and regression-test proposals targeting temporal grounding and conditional reasoning.
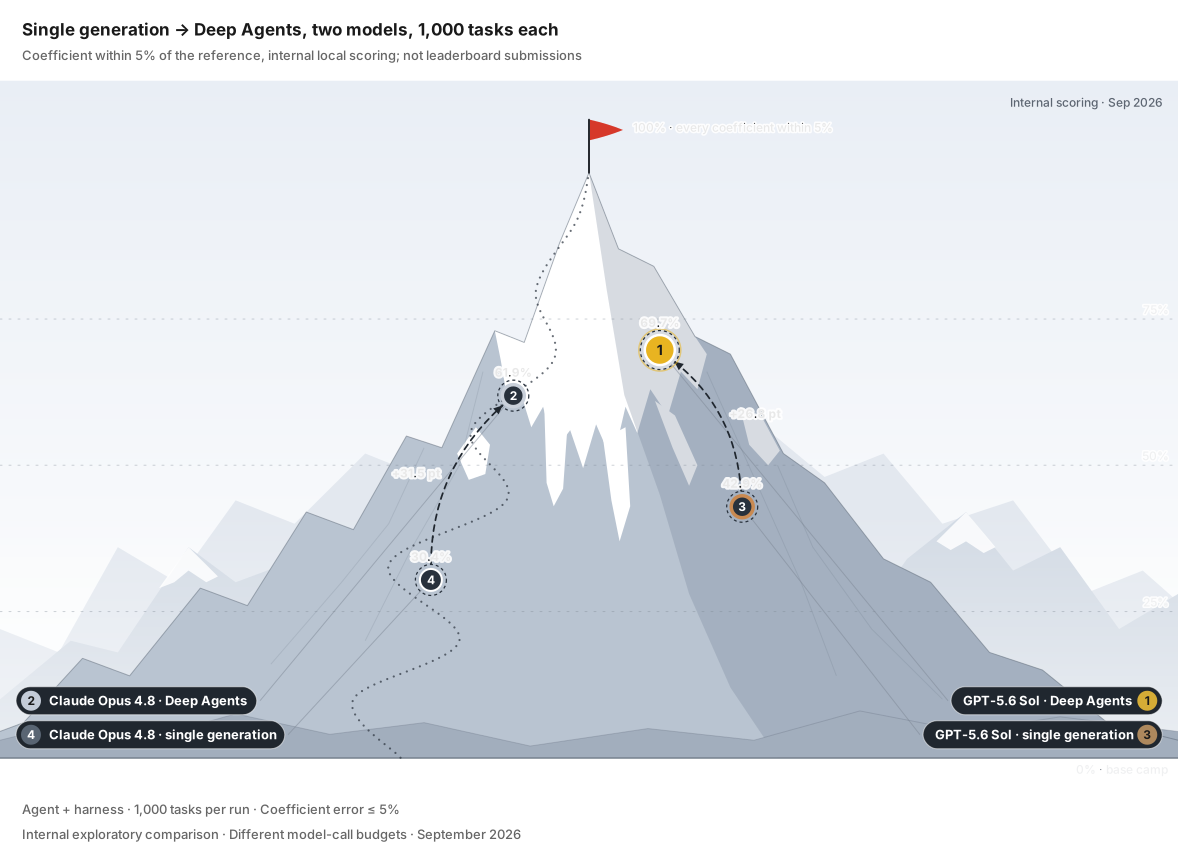
Develop agent-evaluation workflows integrating task ingestion, model-generated analysis, controlled Python execution, and statistical-result validation for empirical economics and finance.
Audit coefficients, standard errors, and significance measures with explicit task denominators, failure classifications, and versioned evaluation artifacts.
HMI Lab, School of Computer Science, Peking UniversityJul 2025–Present
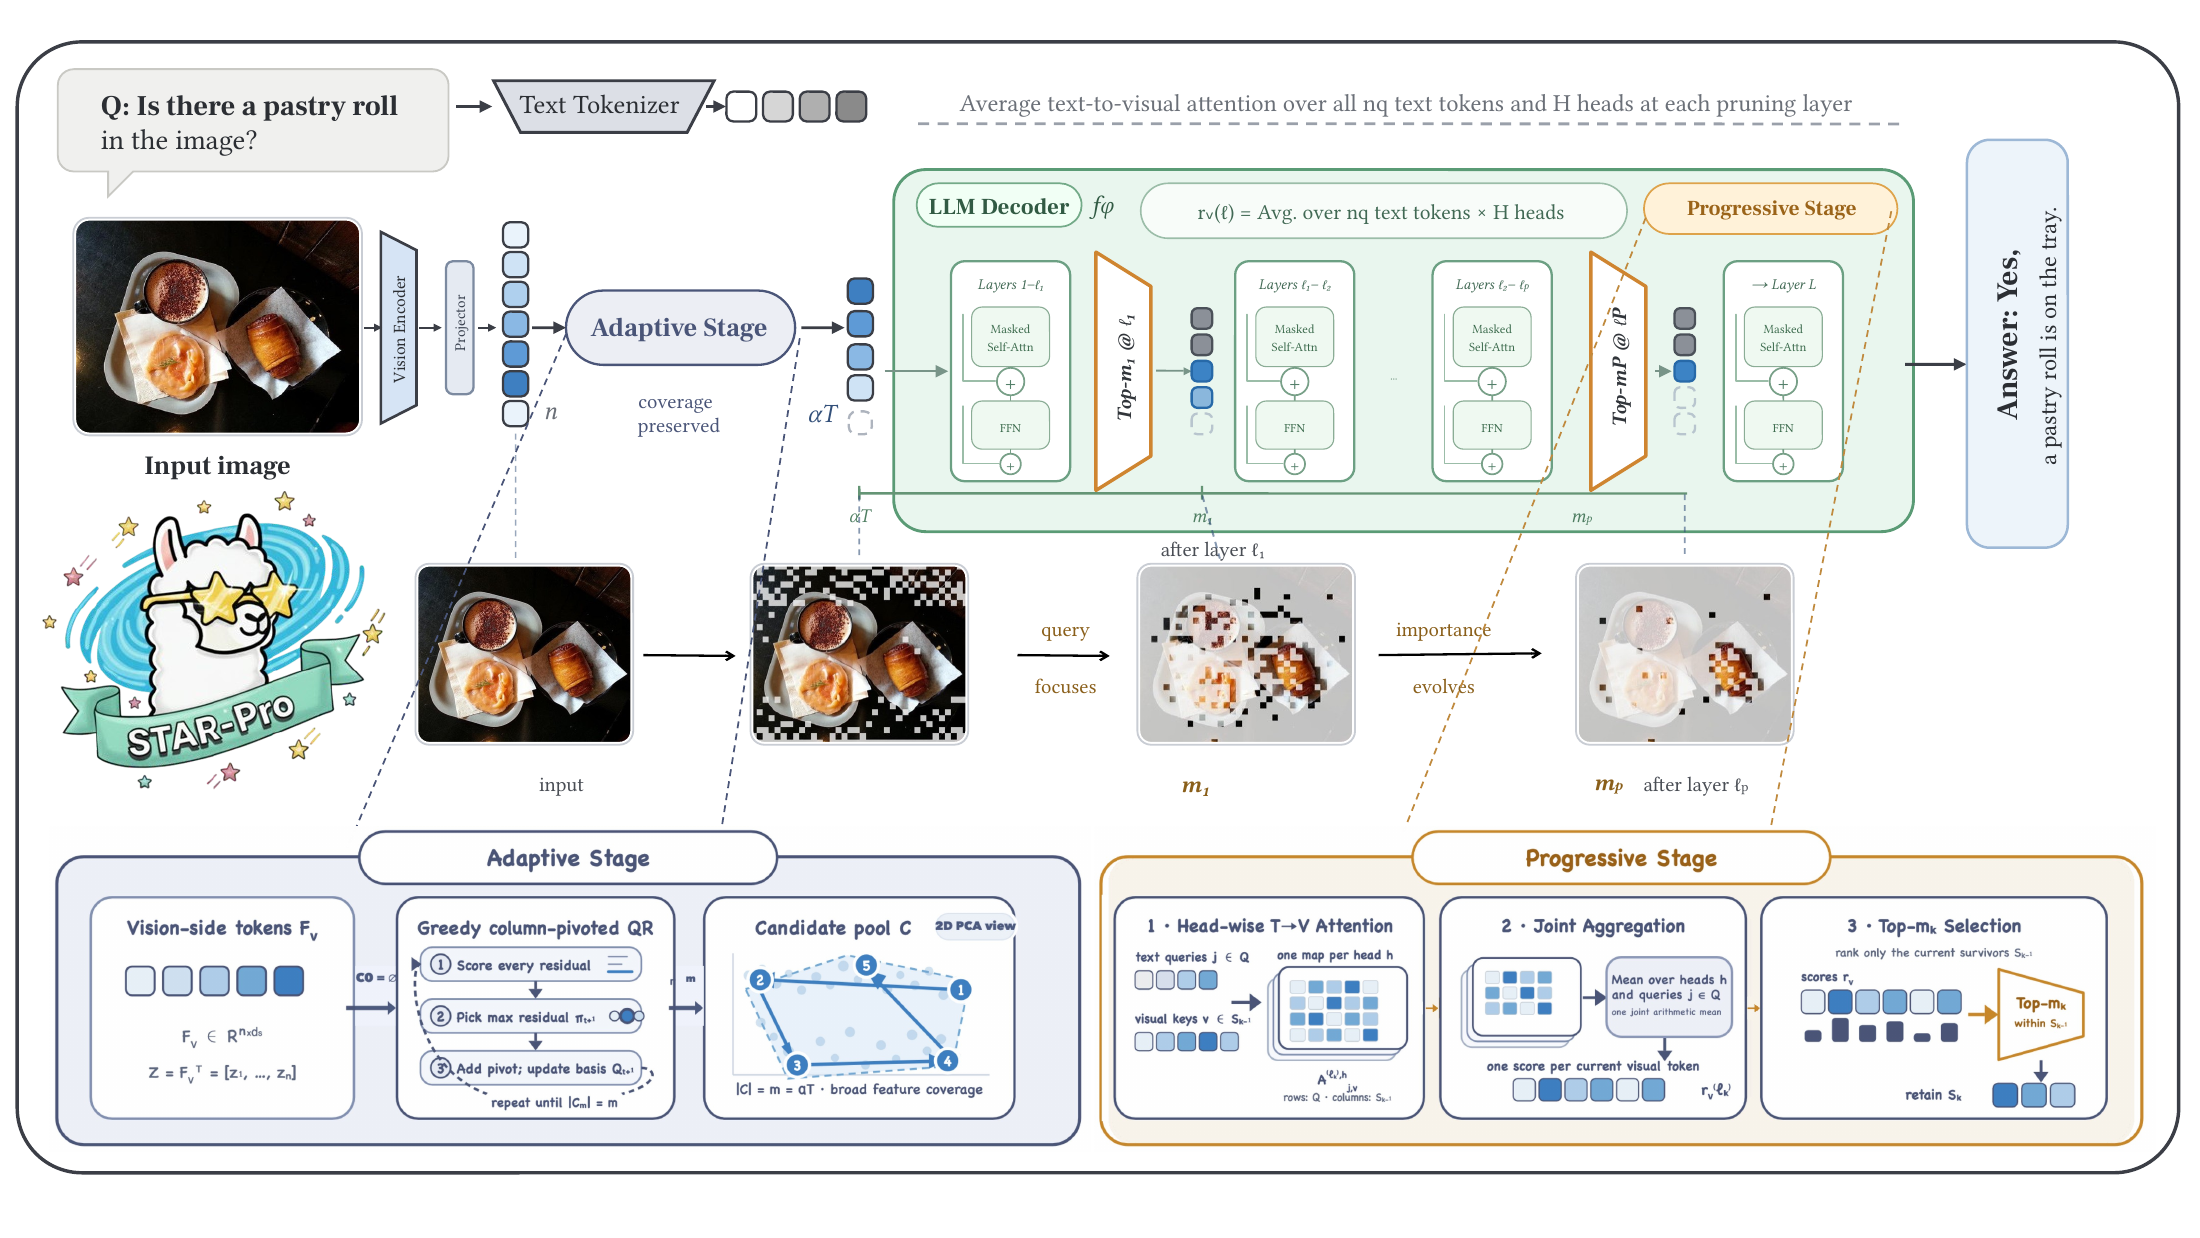
Co-first author of STAR-Pro: adaptive visual-token selection and progressive decoder refinement, evaluated across model architectures for inference efficiency and task accuracy.
Contribute to MiCo / MiCo+ evaluation of training-free visual-token pruning via information-coverage objectives, spanning visual reasoning, grounding, hallucination, and video benchmarks.
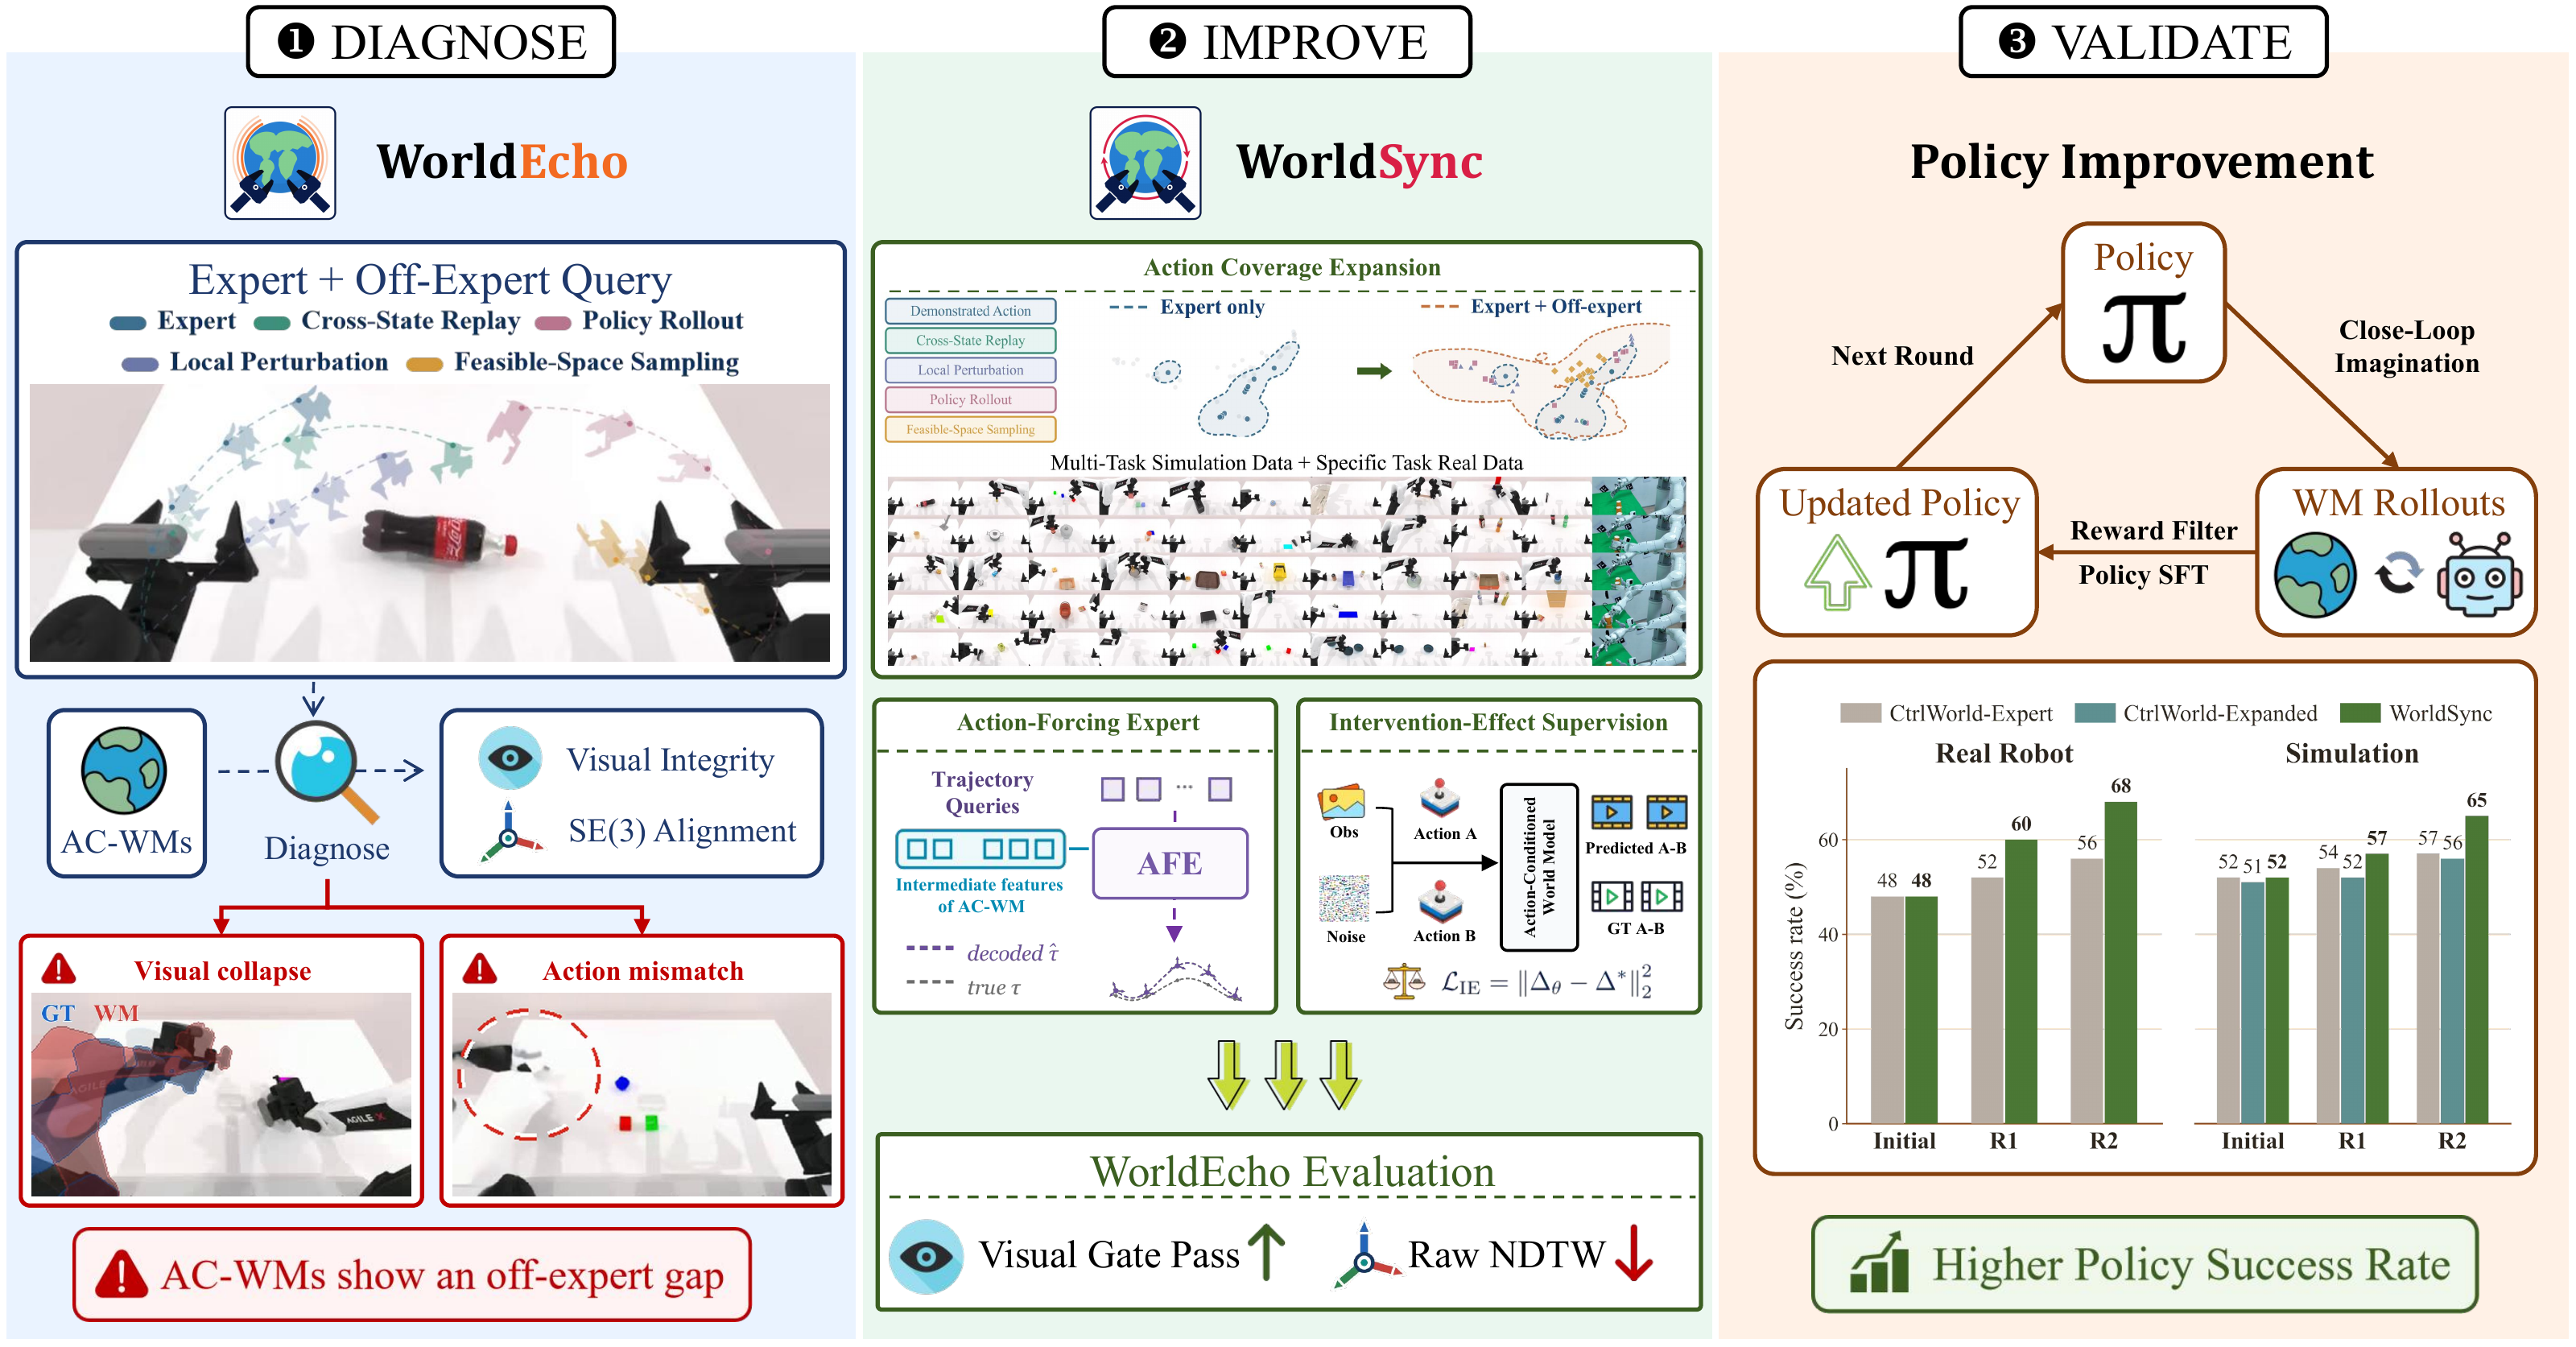
Core contributor to WorldEcho / WorldSync: diagnose action-following errors in robotic world models and study generation alignment for downstream policy learning.
Tencent LightSpeed StudiosAug–Dec 2025
Data Scientist Intern · Singapore
Supervisor: Don Li
Conducted domain-specific LLM post-training for game-related language understanding, content generation, and interactive decision-making.
Built multi-agent economic simulations to study agent coordination and resource-allocation dynamics through structured interactions and environment feedback.
Harvard AI and Robotics Lab, Harvard UniversitySep–Nov 2025
Continue post-visit collaboration as a ReMAP project leader, studying global/local latent visual memory and RL-trained memory-access policies for multimodal reasoning.
Studied multi-image medical reasoning with SFT and GRPO, alongside multi-objective reinforcement learning for financial-agent decision-making.
 arXiv
 Hugging Face