arXiv 2026 · Under review
RegimeVGGT
Layer-Wise Spatially Preserving Redundancy Removal for Visual Geometry Grounded Transformer
Yichen Guo · Co-author
A project overview on Yichen Guo's research homepage, based on the linked paper.
Overview
RegimeVGGT accelerates visual geometry transformers without additional training. It combines layer-dependent token merging with spatially preserving key/value downsampling, reducing redundant computation while protecting cross-view geometry and the information needed for camera pose estimation.
How it works
Identify different roles across layers
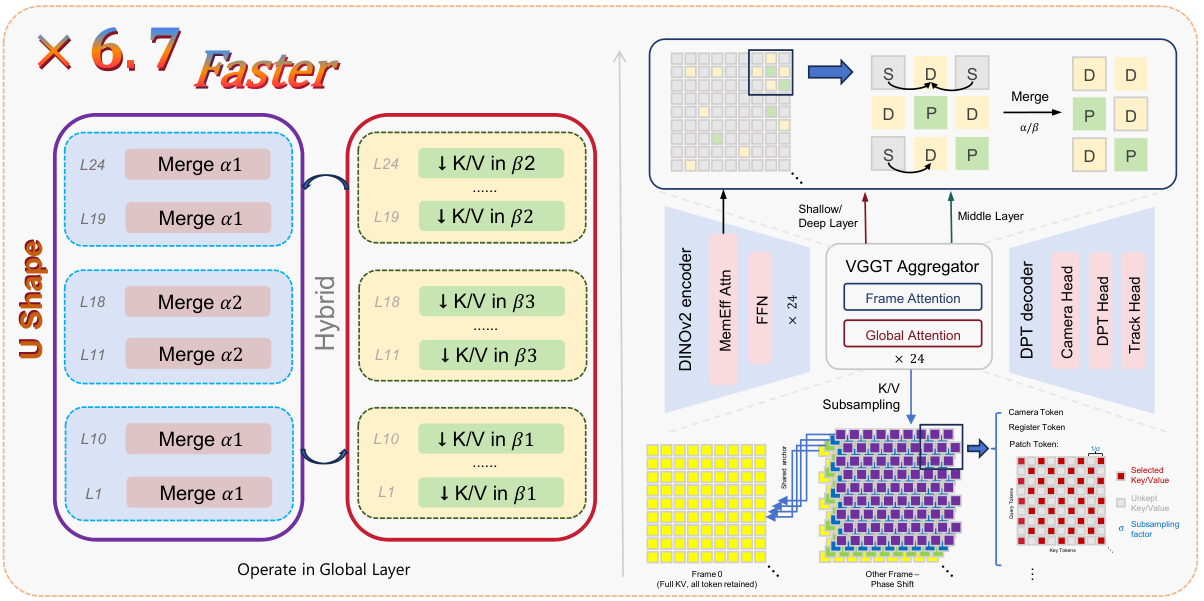
Layer analyses distinguish shallow, middle, and deep regimes. The method uses a U-shaped compression schedule instead of applying one compression level everywhere.
Merge tokens while protecting spatial detail
Saliency-guided banded merging preserves geometry- and edge-relevant tokens when reducing the number of visual tokens.
Downsample keys and values selectively
A phase-shifted spatial grid reduces attention computation, while a full-resolution reference frame and protected camera/register tokens preserve cross-frame coverage and the pose pathway.
Evaluation
The paper examines reconstruction quality, camera pose estimation, and runtime, including long image sequences. Its comparisons and ablations investigate which information must remain available as computation is reduced. Detailed settings and reported results are in the paper.
Paper and resources
RegimeVGGT: Layer-Wise Spatially Preserving Redundancy Removal for Visual Geometry Grounded Transformer
arXiv:2606.18439
Figures and technical descriptions are based on the linked paper. The original author list and publication status are shown above.