CoRL 2026 · Accepted
SafeDojo
Safe Reinforcement Learning for VLA via Interactive World Model
Yichen Guo · Co-author
A project overview on Yichen Guo's research homepage, based on the linked paper.
Overview
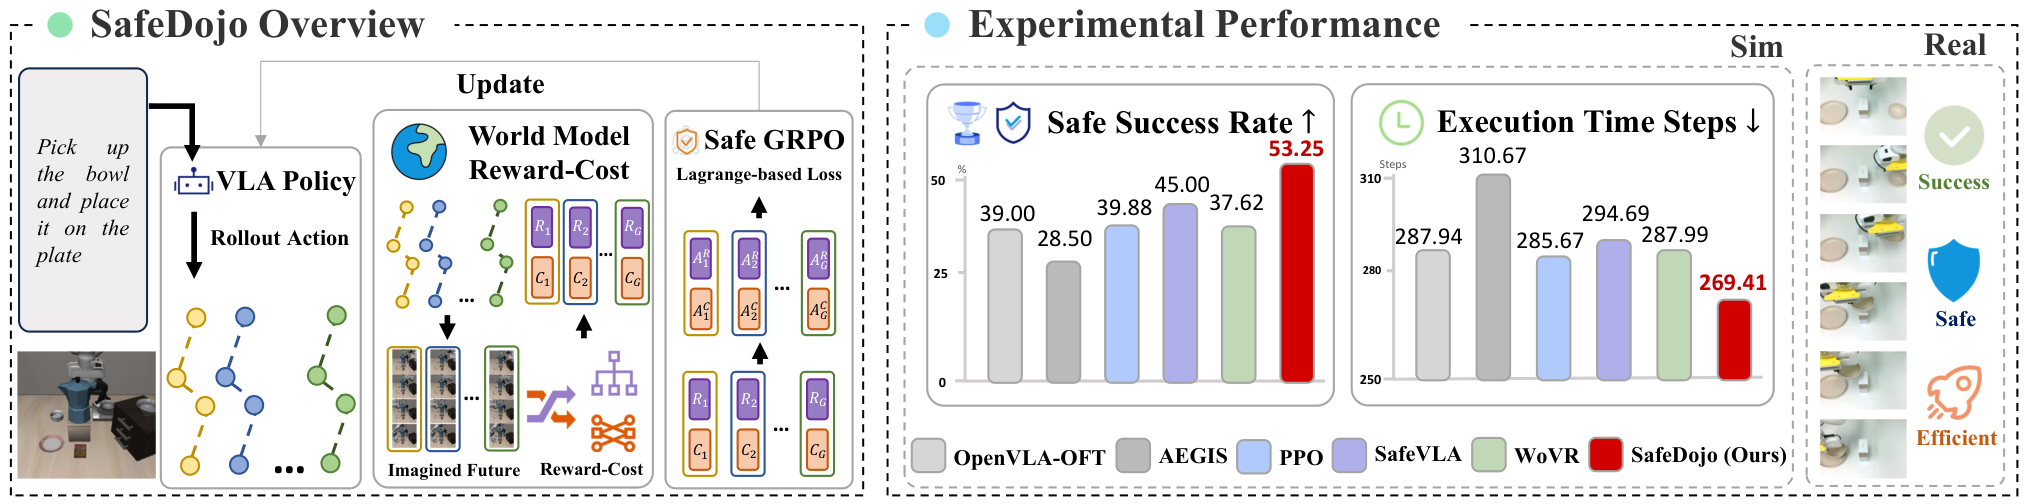
SafeDojo studies how vision-language-action policies can learn safer robot behavior by exploring imagined futures. An interactive world model supplies feedback on both task progress and collision risk, allowing policy optimization to consider these objectives separately.
How it works
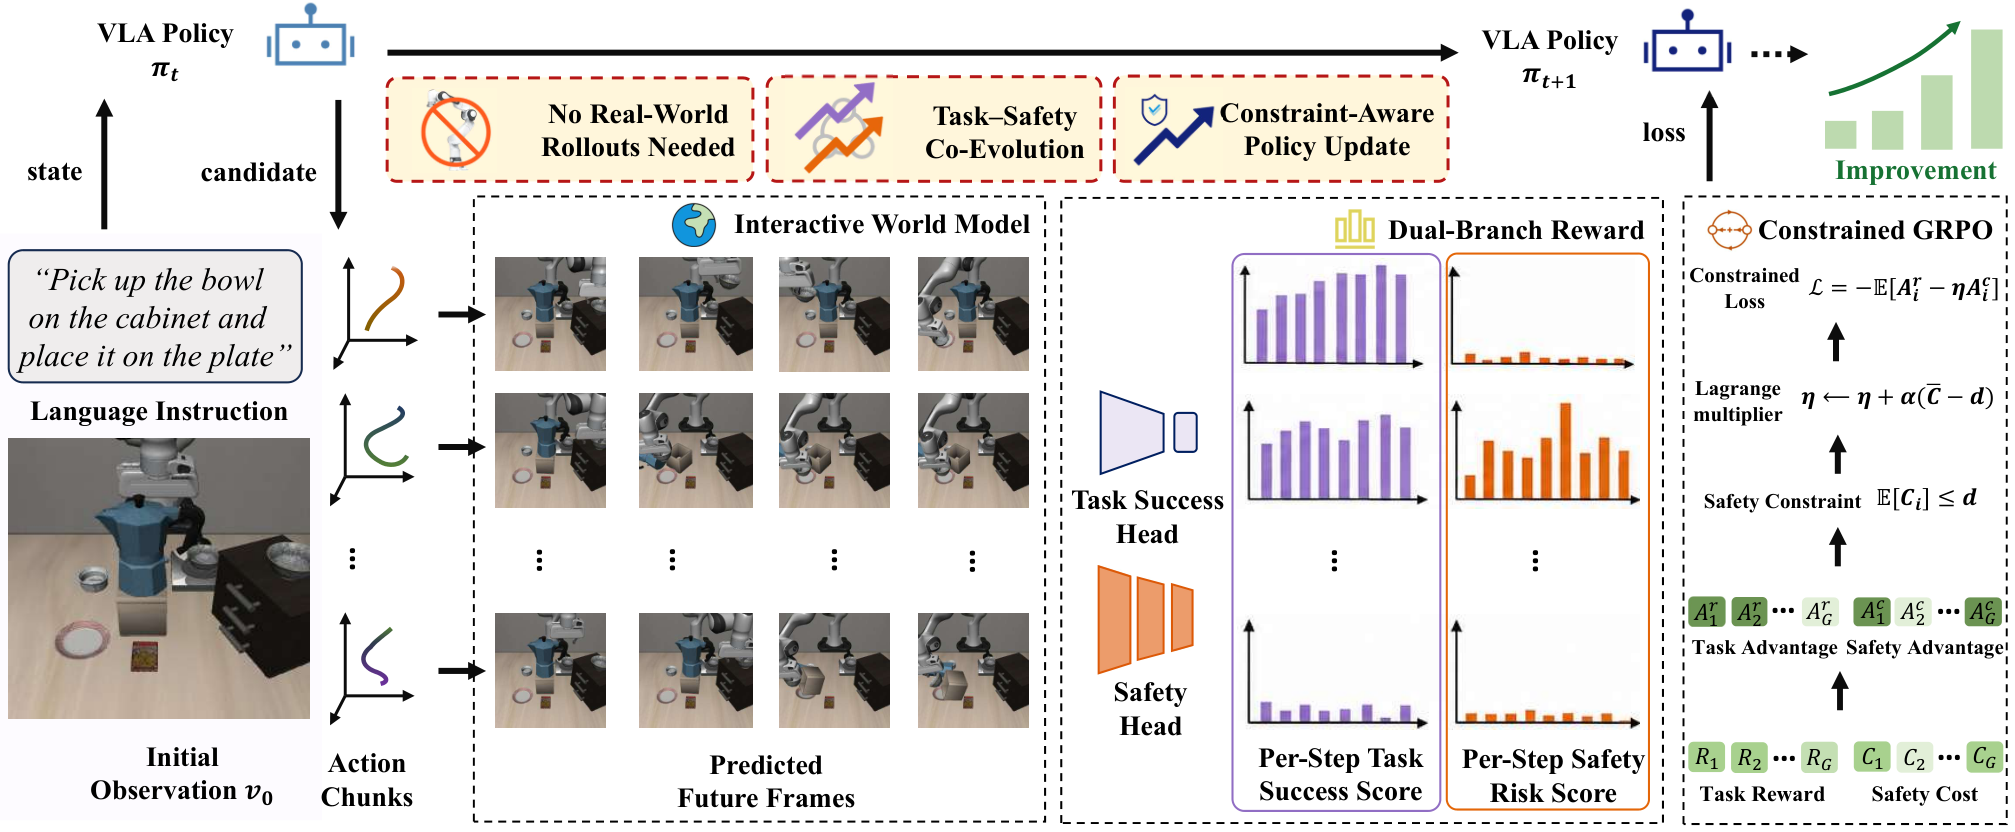
Imagine action-conditioned futures
A VLA policy proposes action chunks. An interactive video world model rolls them forward into predicted observations and latent dynamics.
Evaluate progress and safety separately
A task-success classifier scores imagined frames, while a safety head estimates collision costs from latent context and proposed actions.
Update the policy under a safety constraint
A Lagrangian-based constrained GRPO objective combines the reward and cost signals to improve task completion while controlling safety risk.
Evaluation
The paper evaluates task completion, collision-free completion, and execution efficiency on SafeLIBERO with two obstacle settings, and tests transfer on five real-world Franka tasks. The linked paper provides the full protocols, comparisons, and limitations.
Paper and resources
SafeDojo: Safe Reinforcement Learning for VLA via Interactive World Model
arXiv:2606.20698
Figures and technical descriptions are based on the linked paper. The original author list and publication status are shown above.